What is the softmax function?
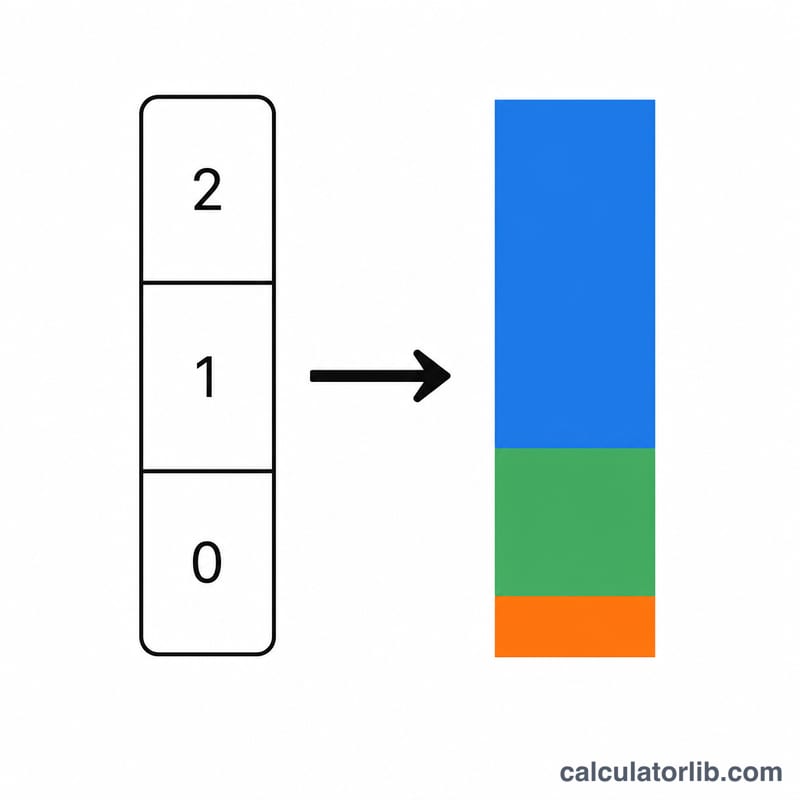
The softmax function takes a vector of K real numbers and turns it into a probability distribution: every output lies strictly between 0 and 1, and all K outputs add up to exactly 1. It is the standard activation function in the output layer of neural-network classifiers, where it converts raw model scores (logits) into class probabilities. Because it is dimensionless, the inputs are pure numbers with no units.
How to use this calculator
Type your input vector into the box as a list of numbers separated by commas, spaces, or new lines (for example 1, 2, 3). The numbers may be positive, negative, zero, or fractional. Press calculate and you will get the softmax probability for each component, the sum of the outputs (which should equal 1), and the argmax — the 1-based index of the largest probability.
The formula explained
For each component j the softmax is $$\sigma(z)_j = \frac{e^{z_j}}{\displaystyle\sum_{k} e^{z_k}}.$$ Exponentiating makes every term positive, and dividing by the total normalizes them so they sum to 1. For numerical stability this calculator subtracts the maximum value \(m\) from every element before exponentiating: $$\sigma(z)_j = \frac{e^{z_j - m}}{\displaystyle\sum_{k} e^{z_k - m}}.$$ The common factor \(e^{-m}\) cancels, giving an identical result while preventing overflow on large inputs.
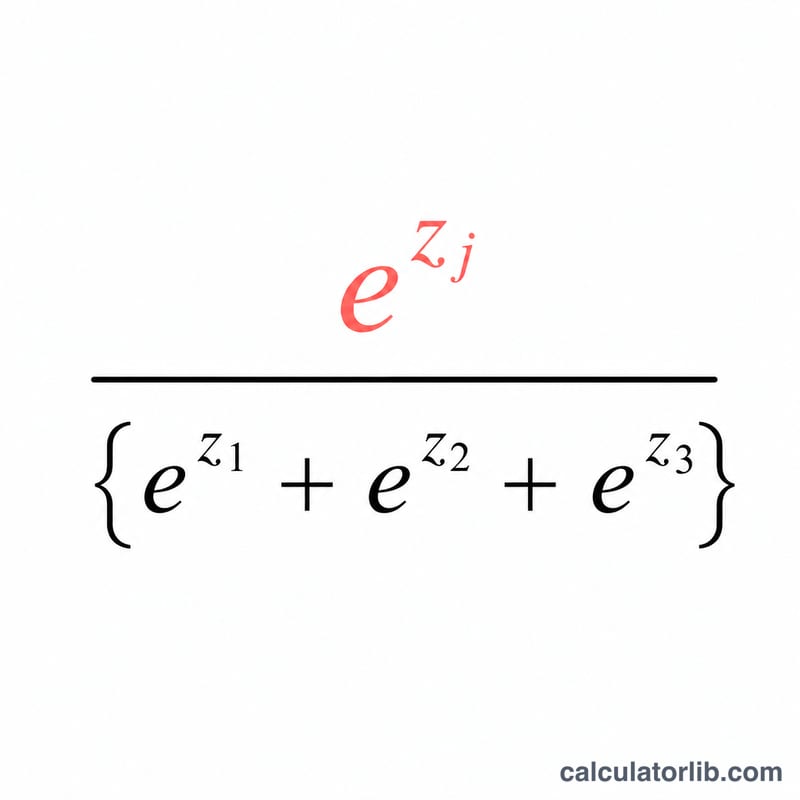
Worked example
For \(z = (1, 2, 3)\): $$e^{1} = 2.71828, \quad e^{2} = 7.38906, \quad e^{3} = 20.08554,$$ summing to \(30.19287\). Dividing each gives $$\sigma = (0.09003,\ 0.24473,\ 0.66524),$$ which sum to 1. The argmax is index 3, the largest input, with probability \(0.66524\).
Softmax Output for Different Input Vectors
The table shows softmax outputs for several input vectors, computed with \(\sigma(\mathbf{x})_i = e^{x_i - \max(\mathbf{x})} / \sum_j e^{x_j - \max(\mathbf{x})}\). Values are rounded to 4 decimals, and the outputs always sum to 1.
| Input vector | Softmax output | Argmax (position) | Comment |
|---|---|---|---|
| (1, 1, 1) | 0.3333, 0.3333, 0.3333 | Tie (all equal) | Equal inputs give a uniform distribution, 1/3 each. |
| (1, 2, 3) | 0.0900, 0.2447, 0.6652 | 3rd | Gaps of 1 between inputs give a moderately confident output. |
| (-1, 0, 1) | 0.0900, 0.2447, 0.6652 | 3rd | Identical to (1, 2, 3) because it is the same vector shifted by 2. |
| (0, 0, 5) | 0.0066, 0.0066, 0.9867 | 3rd | One large input dominates; the two equal inputs share the remainder equally. |
| (2, 4, 6) | 0.0159, 0.1173, 0.8668 | 3rd | The vector (1, 2, 3) multiplied by 2 is sharper. |
| (10, 20, 30) | ≈0.0000 (2.06×10⁻⁹), ≈0.0000 (4.54×10⁻⁵), 1.0000 (0.99995) | 3rd | Nearly one-hot. The max-subtraction trick avoids overflow with large inputs. |
Scaling effect: multiplying every input by a factor greater than 1 widens the gaps between them, so the largest entry gains probability and the distribution sharpens. The ranking (argmax) never changes. Scaling by a factor between 0 and 1 flattens the distribution toward uniform.
FAQ
Why do the outputs always sum to 1? Because each exponential is divided by the sum of all exponentials, the normalization guarantees a total of 1.
What if all inputs are equal? The result is a uniform distribution where every output equals \(1/K\).
Does adding a constant to every input change the result? No. Softmax is shift-invariant: adding the same constant \(c\) to all inputs leaves the output unchanged, which is exactly why subtracting the max is safe.